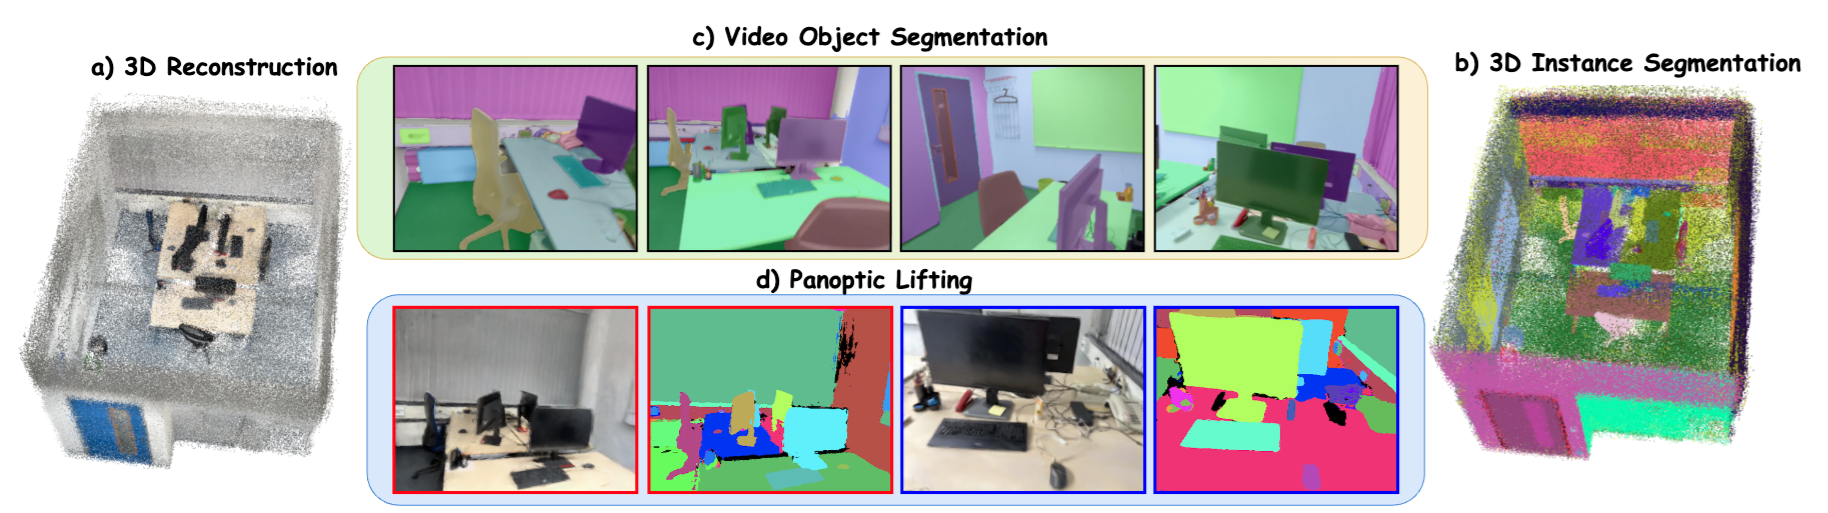
We present SEGA, a geometry-guided framework for 3D instance segmentation of indoor scenes from multi-view image sequences. Existing scene reconstruction and understanding methods typically prioritize either geometric reconstruction or object-level perception, struggling to maintain both globally consistent geometry and coherent instance identities across hundreds to thousands of views. Our key insight is that these objectives are mutually beneficial: geometry provides a robust basis for cross-view instance association, while instance-level perception supplies constraints for refining geometry. SEGA decomposes a long sequence into overlapping clusters, reconstructs local geometry, and predicts 2D instance masks within each cluster. We introduce a 3D-Aware Alignment module that aligns these local predictions with a global proxy geometry and associates instances across clusters, producing temporally coherent video segmentation with globally consistent instance identities. We then apply a post-processing step, Instance-Aware Bundle Adjustment, which uses instance-consistent correspondences to refine the scene geometry. Finally, the predicted video masks are lifted into 3D instance proposals using the reconstructed geometry. We evaluate SEGA on ScanNet200 and ScanNet++v2 across two tasks: class-agnostic 3D instance segmentation and panoptic lifting for novel-view rendering. SEGA achieves state-of-the-art performance, improving Average Precision and Panoptic Quality over the strongest baselines. These results demonstrate the benefits of jointly modeling geometry and instance-level perception for robust indoor scene understanding from long multi-view sequences.
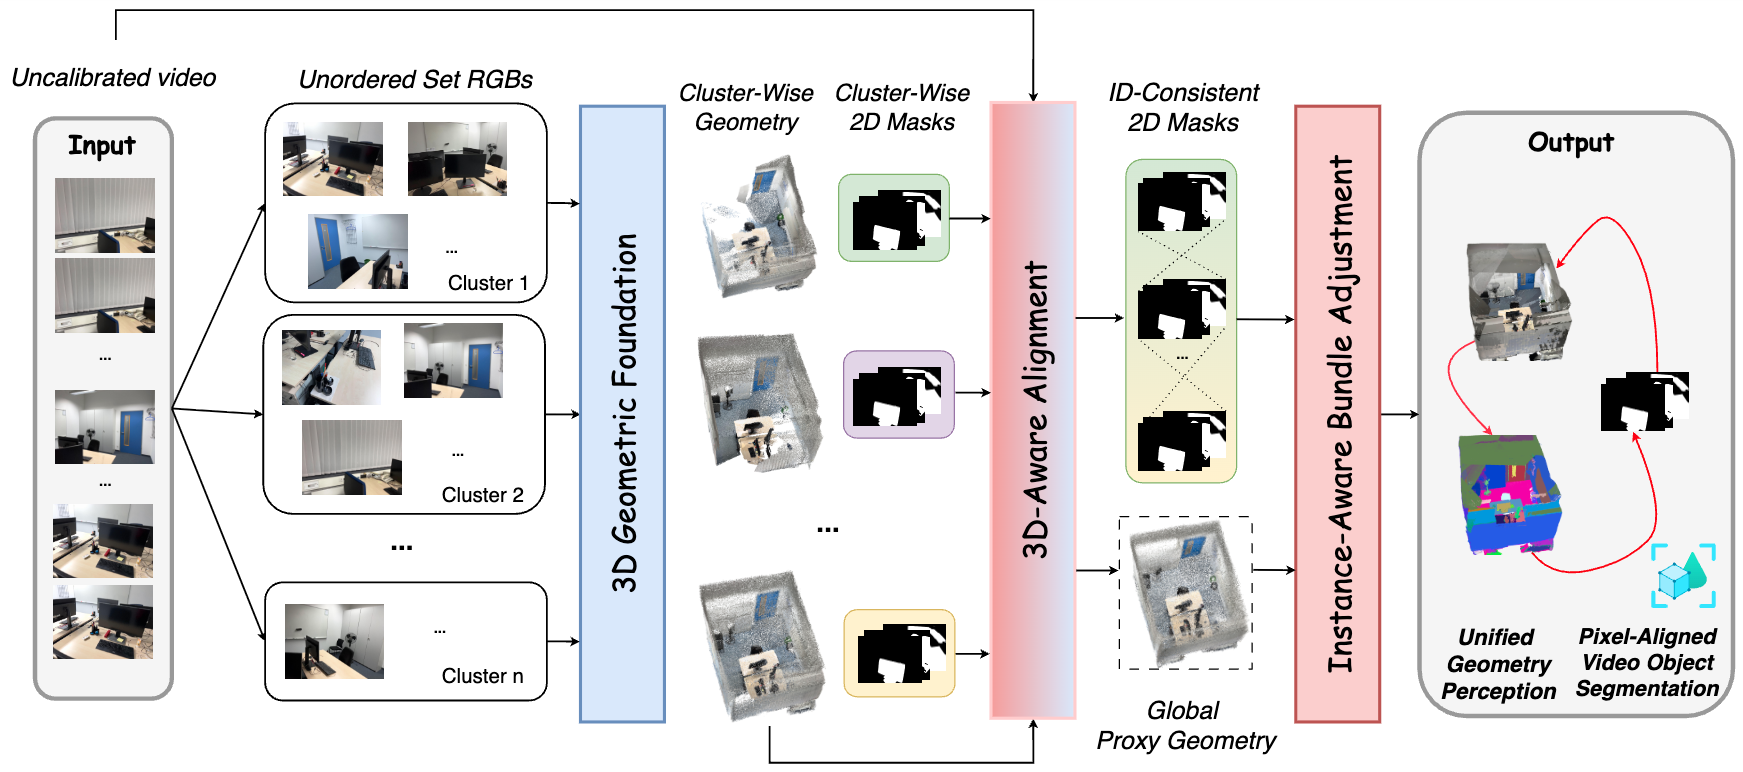
We decompose a given RGB video sequence into overlapping frame clusters and apply a geometric foundation model to obtain cluster-wise geometries and 2D segmentation masks. Our 3D-Aware Alignment module then aligns the fragmented cluster-wise predictions into a unified global proxy geometry and temporally consistent video object segmentation. These consistent 2D priors, together with the proxy geometry, are further used to refine the scene representation through Instance-Aware Bundle Adjustment. The final output is a globally consistent 3D reconstruction with temporally coherent, ID-consistent object segmentation.
| Method | GT Geometry |
ScanNet200 | ScanNet++v2 | ||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| AP↑ | AP50↑ | AP25↑ | AR↑ | RC50↑ | RC25↑ | AP↑ | AP50↑ | AP25↑ | AR↑ | RC50↑ | RC25↑ | ||
| 1. Direct Lifting [44] | × | 1.6 | 3.5 | 8.9 | 4.9 | 7.2 | 13.1 | 0.3 | 0.9 | 1.4 | 3.5 | 4.6 | 5.9 |
| 2. SAM3D [44, 39] | × | 5.2 | 12.7 | 24.7 | 16.6 | 33.3 | 52.3 | 3.3 | 8.8 | 18.9 | 10.9 | 24.4 | 43.4 |
| 3. Open3DIS [1, 44] | × | 7.9 | 18.3 | 34.5 | 17.3 | 32.1 | 47.3 | 7.7 | 16.5 | 29.8 | 14.2 | 25.4 | 37.1 |
| 4. PanSt3R [21] | × | 2.1 | 4.2 | 11.1 | 5.6 | 10.3 | 16.1 | 1.5 | 2.9 | 5.7 | 5.2 | 8.9 | 10.6 |
| 5. SEGA | × | 17.1 | 32.7 | 48.4 | 30.8 | 56.6 | 79.4 | 18.1 | 33.8 | 47.2 | 32.3 | 57.8 | 76.7 |
| 6. Direct Lifting [44] | ✓ | 4.8 | 15.3 | 40.1 | 22.5 | 53.4 | 79.5 | 4.3 | 10.1 | 28.9 | 18.5 | 37.2 | 65.9 |
| 7. Felzenszwalb [43] | ✓ | 4.5 | 9.3 | 26.1 | 8.9 | 18.3 | 50.3 | 4.2 | 8.9 | 22.1 | 8.2 | 17.4 | 42.4 |
| 8. SAM3D [44, 39] | ✓ | 6.7 | 21.7 | 46.4 | 21.6 | 49.9 | 77.6 | 4.7 | 13.0 | 33.0 | 17.6 | 36.8 | 60.6 |
| 9. Open3DIS [1, 44, 43] | ✓ | 29.1 | 44.0 | 49.1 | 55.5 | 83.2 | 92.1 | 21.8 | 38.9 | 46.5 | 42.3 | 75.1 | 88.9 |
| 10. PanSt3R [21, 43] | ✓ | 9.9 | 28.4 | 48.1 | 20.1 | 45.2 | 69.9 | 8.2 | 25.3 | 40.1 | 24.7 | 49.9 | 72.1 |
| 11. SEGA [43] | ✓ | 31.5 | 48.2 | 55.5 | 58.6 | 85.2 | 93.1 | 28.4 | 43.9 | 49.3 | 54.2 | 82.7 | 92.1 |
Left drag: rotate | Right drag: pan | Wheel / trackpad: zoom
Left drag: rotate | Right drag: pan | Wheel / trackpad: zoom
Left drag: rotate | Right drag: pan | Wheel / trackpad: zoom
Left drag: rotate | Right drag: pan | Wheel / trackpad: zoom
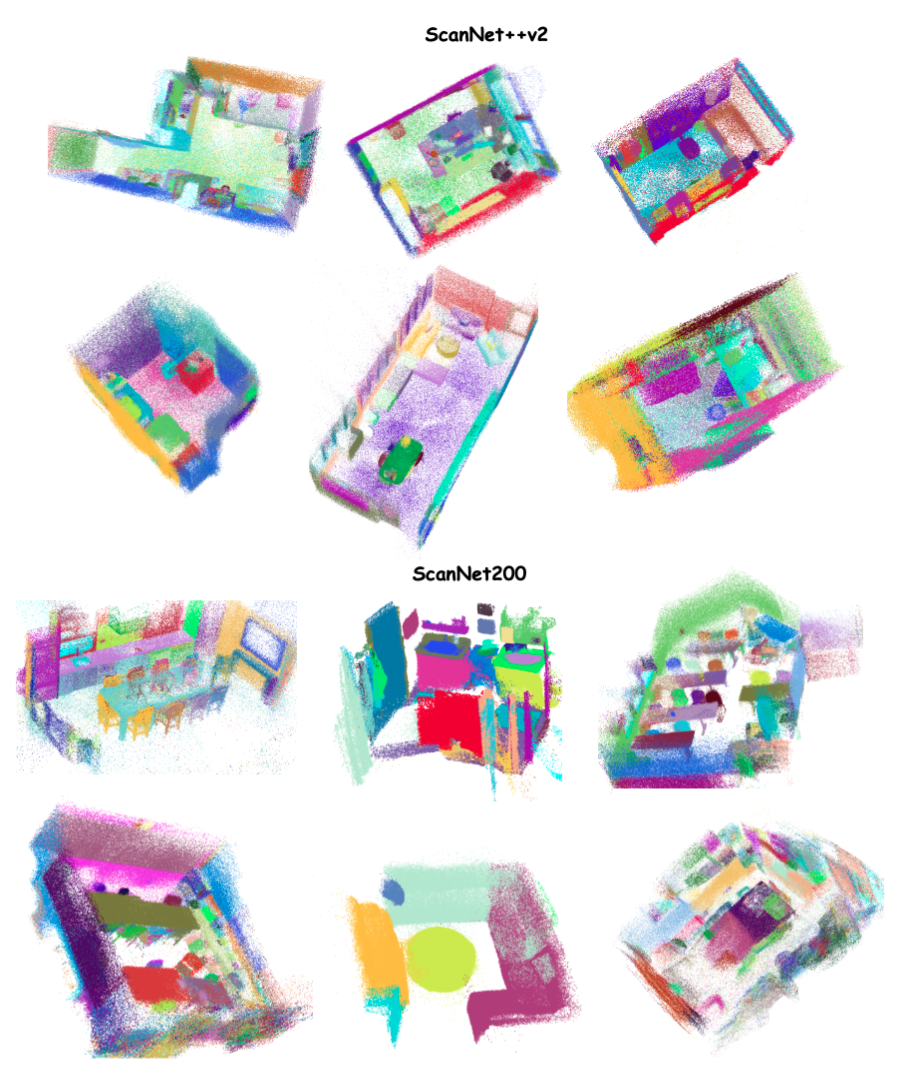
Click the figure to view more qualitative results.
The source code is built upon Open3DIS, PanSt3R, MERG3R and Gaussian Grouping.
We thank Tuan Duc Ngo, Lojze Zust, Heechan Yoon, Ruohan Gao for early valuable discussions.
We thank Trinh Huynh for valuable help on the demo.